A network on chip in TxHDL, with a CPU and a GPU on it
A conventional interconnect connects multiple peripherals to a single host. A network on chip (NoC) connects multiple hosts and peripherals across a 2D mesh topology, routing packets between arbitrary endpoints. We implemented a packet-routed NoC in TxHDL. The design features four-neighbor mesh routing, dual virtual channels, dimension-order routing, and protocol bridges that map AXI4 transactions to network packets. To validate the architecture, we placed our RISC-V core, GPU rasteriser, shared memory, and a serial port on the four corners of a 2-by-2 mesh. The CPU computed a 3D icosahedron model and generated display lists that the GPU rendered across the network.
Mesh nodes and physical links
Each mesh node maintains bidirectional physical links with four adjacent neighbors. A fifth local port connects to attached compute units or memory peripherals. Links transfer individual packets, where each packet encapsulates one beat of an AXI channel. Packets contain destination node coordinates and source return stamps.
Embedding the source identifier in the packet header eliminates routing state tables in intermediate switches. Responses read the return coordinates directly from the incoming request header to find their way back to the originating host.
Every physical link provides two independent virtual channels for request and response traffic. The switch maintains separate queues and buffers for each virtual channel. Separating request and response traffic prevents protocol deadlocks. If request queues fill completely, responses still flow freely through the independent response network, ensuring outstanding transactions can retire and clear upstream buffers.
Dimension-order routing
Packets navigate using deterministic dimension-order routing (X-then-Y). A packet travels horizontally (east or west) until reaching its target column. It then travels vertically (north or south) until reaching its target row, entering the local port at its destination. Routing decisions evaluate simple coordinate comparisons.
Dimension-order routing on a 2D mesh is provably deadlock-free without complex virtual channel allocation. Because packets never turn from vertical back to horizontal paths, cyclic dependency chains cannot form in the channel resource graph.
Each router switch transfers one packet per clock cycle. For every input queue, the switch evaluates destination port availability, ensuring blocked outputs do not stall independent routes. When multiple inputs contend for the same exit, a fixed-priority arbiter prioritizes network-through traffic over local injection, preventing local nodes from starving transit paths.
AXI protocol bridges
The local exit port interfaces with standard AXI4 buses via a bidirectional protocol bridge:
- The host bridge translates AXI address and data phases into network packets. Its internal routing table maps addresses to destination node IDs, using a default route for external memory regions. Single-beat writes pack address and payload data into a single packet, preventing interleaved writes from colliding at the target peripheral.
- The peripheral bridge reconstructs AXI transactions from incoming packets and routes responses back to the original source node. The bridge renames transaction IDs dynamically. Because distinct hosts may allocate identical transaction IDs, the bridge assigns unique local IDs, maintaining a lookup table that maps each local ID to the original source node and host transaction ID.
Endpoints remain decoupled from network topology. Hosts and peripherals communicate through standard AXI interfaces, unaware that packets traverse multi-hop network switches.
Multi-core mesh demonstration
The reference demonstration deploys a 2-by-2 mesh topology:
- Node (0, 0): Vreteno, the RV32IM RISC-V core.
- Node (1, 0): Razboj, the graphics rasteriser.
- Node (0, 1): shared system memory.
- Node (1, 1): the serial UART controller.
Compute units interact exclusively through shared memory across the network. Software running on Vreteno defines an icosahedron model with twelve vertices and twenty triangular faces. The core applies 3D rotation transforms, performs back-face culling, and calculates surface illumination. It writes the visible triangles to shared memory as an assembled display list, setting the primitive count last. Razboj polls the primitive count across the mesh. When the count becomes non-zero, Razboj fetches the display list over the network and renders the image into the framebuffer.
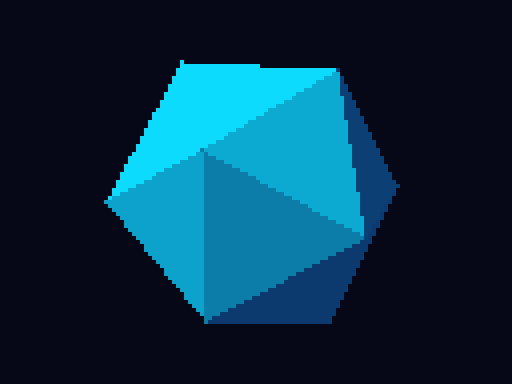
Neither Vreteno nor Razboj required modifications to run on the network. Each node instantiates the same three modular blocks: the compute core, a protocol tracker, and an AXI bridge.
Mesh testing uncovered a pipelining bug in the RISC-V core. When a multiply instruction immediately followed a memory load, the execution stage read stale register values because the load was still traversing the multi-hop network. The hazard detection logic now stalls correctly on pending network loads.
Network latency and throughput
Comparing mesh rendering against a direct point-to-point bus reveals the latency characteristics of the NoC. On the 2-by-2 mesh, Razboj takes approximately twice as long to render the scene compared to a dedicated bus connection.
This latency reflects hop counts and switch bandwidth limits. Each switch hop adds fixed cycle delays to memory round trips. While the CPU stalls on individual read responses, the rasteriser streams more than 12,000 pixel writes without awaiting acknowledgments. Its rendering speed is bounded by router throughput: one packet per switch per clock cycle. Upgrading switches to multi-port crossbars would allow concurrent transfers across independent ports.
Current design limits and future work
The current NoC prototype includes several deliberate simplifications:
- Mesh topology is instantiated via simulation helpers; FPGA synthesis will wrap the topology inside a single lowered TxHDL module.
- Multi-beat write bursts are not yet supported over the packet network, requiring single-beat transactions for writes.
- The switch arbiter uses fixed priority rather than round-robin scheduling.
The NoC chapter of the TxHDL documentation provides complete source code and architecture specifications, mirrored in the repository.